How AI Data Annotation Improves Multilingual Translation
Introduction
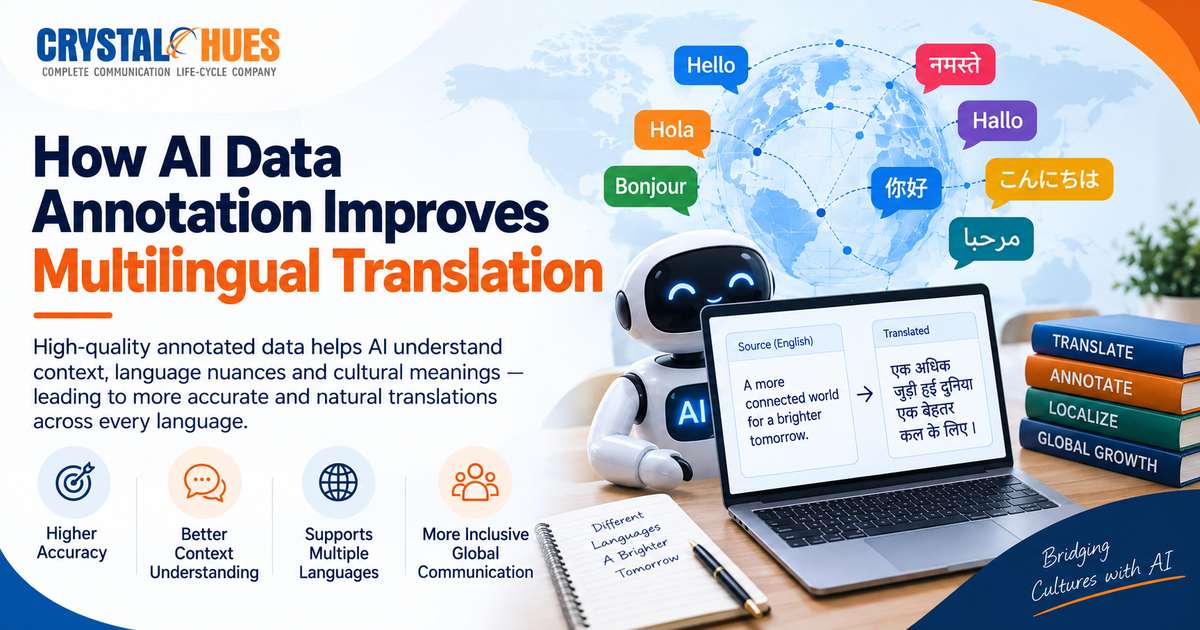
LLMs are supposed to give accurate and contextual outputs requiring quality and labelled data as inputs. Ask any team building multilingual AI tools what decides whether the output sounds natural or clunky, and the answer rarely starts with the algorithm. It starts with the data behind it. AI data annotation, the process of labelling and structuring language data so machines can learn from it, quietly determines how well a translation system understands tone, context and meaning across languages. This piece looks at what annotation does, why it matters more than most people assume, and how it connects to the broader work of multilingual translation.
What Is AI Data Annotation?
AI Data Annotation is the process of labelling raw data so a machine learning model
can learn patterns from it. For language data, this might mean tagging parts of
speech, marking sentiment, identifying named entities like people or places, or
flagging where one language's grammar structure diverges from another's.
Think of it as teaching by example. A translation model never learns grammar rules the way a student does. It learns from thousands of labelled examples showing what correct, context aware language looks like. Annotation is the step that turns raw, unstructured text into something a model can learn from.
Why Data Quality Matters for AI
Translation
A model is only as good as the data it
trains on. Feed a translation system inconsistent, poorly labelled or narrow
data, and it produces exactly what you would expect: shaky translations that
miss context, mishandle idioms, or default to overly literal phrasing.
This becomes especially visible across less
common language pairs. Widely spoken languages tend to have abundant training
data, so models handle them reasonably well. Languages with smaller digital
footprints often lack that depth, which is exactly where careful,
well-structured annotation makes the biggest difference. Quality here means
more than volume. Consistent labelling, accurate context tagging and broad linguistic
coverage all shape how reliably a model performs once it moves from training
into real world use.
How Annotation Improves
Multilingual Translation
Good annotation touches several layers of a
translation system at once. Entity labelling helps a model recognise that a
name, a place or a brand should stay unchanged across languages rather than
being awkwardly translated. Intent and sentiment tagging help a model
understand tone, so a formal business email and a casual social post get treated
differently even when the underlying vocabulary overlaps.
Context annotation is arguably the most
important layer for multilingual work. Many languages depend heavily on
surrounding context to resolve meaning, something word for word translation
consistently gets wrong. Annotated examples that capture full sentences and
their surrounding context give a model the reference points it needs to make
better judgment calls, rather than defaulting to the most literal option.
Linguistic nuance annotation rounds this
out, covering things like regional variation, formality levels and idiomatic
expressions that resist direct translation. None of this happens automatically.
It requires structured, carefully reviewed data annotation services built specifically
around language data rather than generic labelling.
Data Annotation vs Translation vs
Localization
These three terms get used interchangeably,
which creates unnecessary confusion. Annotation is the preparatory step, where
language data gets labelled and structured so a model can learn from it,
happening before a model ever learns. Translation is the act of converting
content from one language into another, whether done by a person or a machine,
happening during the actual content conversion. Localization goes a step
further, adapting content for cultural, regional and contextual relevance
beyond linguistic accuracy alone, happening after translation to fit a specific
market.
Understanding where each piece fits matters
for any team building or buying multilingual AI capability. Crystal Hues' Data Text Translation & Localization
work sits across the translation and localization stages, handling multilingual
text adaptation alongside the regional and cultural adjustments that pure
translation alone never covers.
How Human Review Supports AI
Translation Quality
Even well-trained models benefit from human
eyes on the output. This is where machine translation post editing enters the
picture, where a linguist reviews and refines AI generated translation before
it reaches its final audience. Post editing catches the kind of context slips
that a model can still make, particularly in specialised or high-stakes content
where a wrong word choice carries real consequences.
Human review also feeds back into the
system over time. Corrections and refinements made during review can inform
future annotation and training cycles, gradually improving how a model handles
the language pairs and content types it sees most often.
What Businesses Should Look for
in Multilingual AI Data
Teams evaluating multilingual AI data or
annotation partners should look for a few specific things. Language coverage
matters, since broad coverage across the languages a business operates in
outweighs a large but narrow dataset. Annotation consistency matters just as
much, since inconsistent labelling introduces noise, a model must work around
rather than learn from.
Where the underlying training data comes from also deserves attention, since reliable AI data collection and sourcing practices shape everything built on top of that data later. A clear quality assurance process, ideally one that includes human review at key stages, rounds out what a solid multilingual AI data setup looks like.
FAQs
What is AI data annotation?
It involves proper labelling of raw data so
that models can understand and recognise patterns from it.
Why is data annotation important for
machine learning?
Models require identification of data to
produce accurate and contextual outputs so annotating raw data helps them with
learning the patterns and make them better.
How does data annotation improve AI
translation?
Annotation labels entities, sentiment, intent
and context within language data, giving translation models the reference
points needed to handle meaning and tone accurately across languages.
What is multilingual AI?
Multilingual AI refers to systems trained to
understand, process or generate content across more than one language, relying
on annotated data covering each language involved.
What is the difference between data
annotation and translation?
Annotation labels and structures data so a
model can learn from it, while translation is the actual conversion of content
from one language into another.
Can human annotation improve translation
quality?
Yes.
Human review and post editing catch context and nuance issues a model can still
miss, and corrections from that process can inform future training cycles.
Conclusion
Multilingual AI translation depends on the quality, structure and consistency of the data that trained it in the first place. As businesses lean further into AI for multilingual communication, the work happening upstream, in annotation, labelling and data quality, deserves just as much attention as the translation output itself. Crystal Hues works across this full picture through its broader Data Services, supporting businesses building reliable multilingual AI capability from the data layer up.